Evaluation Experiment
My AI judges agreed with themselves. Not with each other.
Each judge mostly agreed with itself. On borderline cases, they often didn't agree with each other, and that difference alone moved a pass rate by 27 points.
• Four AI judges marked the same 30 items 13 times each. On clear-cut items they were usually right, and asked again, each mostly gave the same mark.
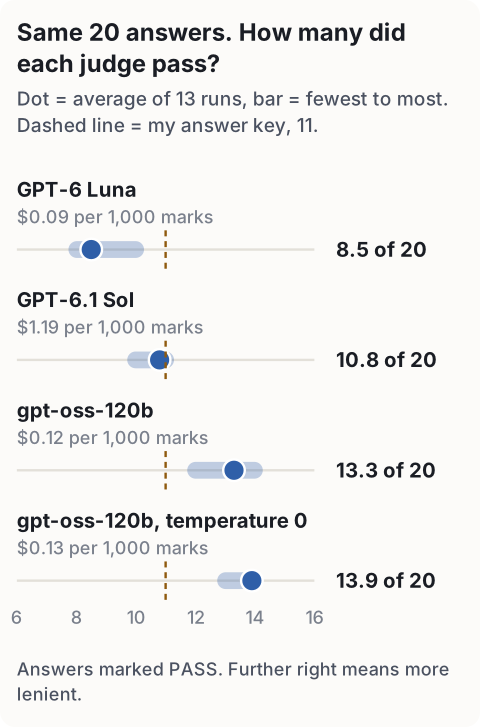
• They didn't agree with each other. On the same 20 answers, one judge passed 8.5 on average and another 13.9. Swap one for the other and a pass rate moves 27 points with nothing else changing.
• So the judge is part of your metric. Write down the model and settings, run more than once, and put your strictness in the marking guide.
If you build with AI, you soon need to check whether its answers are any good. Checking thousands by hand is slow, so many teams use a second model to do the marking. This is called an LLM judge: one model writes the answers and another marks them, like a teacher marking homework.
I wanted to know four things about these judges. How often are they right? How well do they score summaries, where there's no simple right answer? Ask the same judge the same question 13 times: do you get the same mark? And on borderline cases, do different judges agree?
My first test was too easy
I started with 30 short questions and answers, some right and some wrong, and gave the judges the correct answer to compare against. Three models marked each one 13 times. After 1,560 marks, not one had changed, and every model was right every time.
That mostly told me the test was too easy. When the judge has a correct answer to compare against, the job is simple. Real checking rarely looks like that, so I built a harder test.
What I tested
Thirty new items, based on three checks real AI systems need. All the documents are made up; none come from a real company.
- Document checks (10). A chatbot answers a question from a company's help pages. Is every claim in the answer actually in those pages? This is often called faithfulness. PASS or FAIL.
- Summary scores (10). The judge scores a summary of an incident report or meeting notes from 1 to 5 against a written marking guide.
- Policy checks (10). A customer-service agent replies to a customer. Does the reply follow every rule in the returns policy? PASS or FAIL.
For 18 items there's a clear right answer. The other 12 are borderline on purpose: cases two careful people might mark differently. Four judges marked every item 13 times:
- gpt-oss-120b, an open model run on Groq: cheap and fast.
- gpt-oss-120b at temperature 0. Temperature controls how random a model's answers are; 0 is meant to make them as repeatable as possible.
- GPT-6 Luna, OpenAI's cheap model.
- GPT-6.1 Sol, a bigger OpenAI model at about nine times the price of gpt-oss.
A typical clear item: the returns policy allows a goodwill voucher of up to £10 when the company made a mistake, and more needs a team lead. The customer's order arrived two weeks late; the agent added a £15 voucher. Correct mark: FAIL. All four judges gave FAIL in all 13 runs. Most clear items looked like that.
1. How often was the judge right?
To keep it fair, I count only the 12 pass-or-fail items where I'm sure of the answer (I explain below why one more item dropped out). Averaged over 13 runs:
- GPT-6.1 Sol: 12 of 12, in every run.
- gpt-oss-120b: 11.2 of 12.
- gpt-oss-120b at temperature 0: 11.1.
- GPT-6 Luna: 11.1.
The misses were telling. A travel policy said first class is allowed for journeys of 3 hours or more, or when it costs no more than 10% extra. The answer being marked said first class is "only" allowed for 3 hours or more. That's wrong, because of the second condition. gpt-oss passed it in most runs; at temperature 0 it passed it 12 times out of 13. More consistent, but consistently wrong.
Luna erred the other way. A reply to "you sent the wrong colour" offered a full refund and a £10 voucher: within the rules. Luna failed it in 11 runs, worried that the agent hadn't checked the 30-day return window, even though the mistake was the company's.
2. How well did they score summaries?
Summaries are harder to mark. There's no single right answer, only a guide: 5 covers what happened, the impact, the causes and the actions with no errors; 4 has one minor omission; 3 misses one key element or has a minor error; 2 has a significant error; 1 is mostly wrong. I wrote ten summaries of two documents, two complete and eight with a specific flaw.
Every judge caught the plain factual errors: all four gave the summary with the wrong cause a 2 in every run. A summary that invented a decision ("the team decided to build fuzzy search") was mostly caught too, though gpt-oss gave it a 4 twice, noticing something was missing but not the invented fact. The judges split on the borderline ones. Every score is on GitHub.
And twice the judges caught me. My "complete" incident summary left out that about 60% of affected customers retried successfully. Luna and Sol gave it 4 in every run, and they were right.
3. Same judge, same question, 13 times
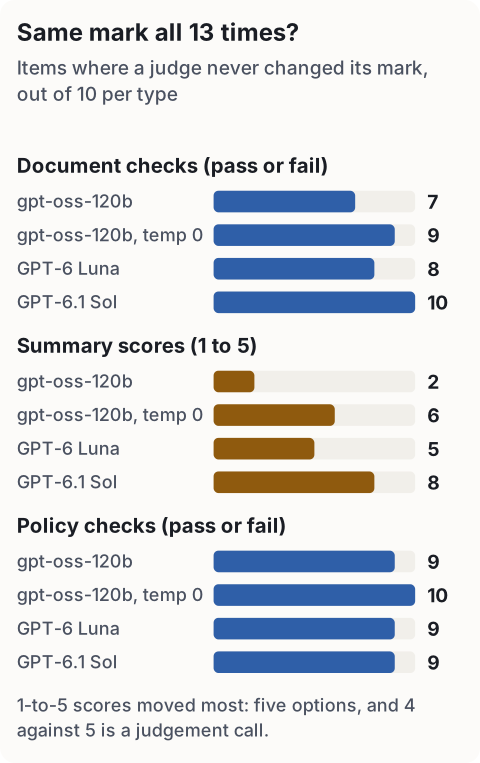
On its default setting, gpt-oss changed its score at least once on 8 of the 10 summaries. Temperature 0 helped, taking it from 18 steady items out of 30 to 25, but didn't fix it. Luna won't let you use temperature 0 at all: the API only accepts its default.
One summary shows what that means in practice. It had everything important, with numbers rounded ("about 4,000 failures over roughly 20 minutes"). I scored it 4. gpt-oss gave 5 seven times and 4 six times: run your evaluation twice and this item alone moves your average. At temperature 0 it gave 5 every time, while Sol gave 4 every time. Steady, but not in agreement.
4. On borderline cases, do the judges agree?
On 12 of the 18 clear items, all four judges' usual marks matched. On the 12 borderline items, they agreed on just 3.
The splits weren't random. On 7 of the 9 items where they split, the two gpt-oss judges sat on one side and the two OpenAI models on the other. One example: API documentation says to wait for the number of seconds in the Retry-After header before retrying. The answer says that, then adds "exponential backoff on top is good practice". Advice the documents never mention. Both gpt-oss judges passed it; Luna and Sol failed it in every run. Neither side is wrong. My marking guide didn't say how strict to be.
The expensive model has blind spots too. A reply promised a refund "within 5 working days, often sooner", against a rule that says not to promise faster refunds. Three judges failed it every time. Sol passed it 11 times out of 13.
Put the splits together and you get the chart at the top. If your quality score were the share of answers passing, swapping Luna for gpt-oss at temperature 0 would move it from 42% to 70%, with nothing in your product changing. That's 27 points.
Is that just because I wrote borderline items on purpose? Partly. Of the 5.4-answer gap between those two judges, 3.0 came from the 7 borderline items and 2.4 from the 13 clear ones. On clear items alone, Luna passed 50% and gpt-oss 68%: still about 18 points, mostly because Luna is the strictest judge. Real evaluation sets usually have fewer borderline cases than mine, so expect a smaller gap, but not zero.
Where I was wrong
I read the judges' reasons wherever they disagreed with me, and four of my own marks didn't hold up:
- My "complete" incident summary left out a key figure. 4, not 5.
- My "complete" meeting summary turned "fuzzy-matching changes can only ship at weekends" into "search changes ship at weekends". Imprecise, as Sol said.
- One document answer, "webhook deliveries don't count at all", can be read as claiming more than the documents say. That's the item I dropped from the accuracy count.
- On one borderline summary I gave 4 where my own guide says 2.
When a judge disagrees with you, read its reason before deciding which of you is wrong.
What I'd take away
- The judge is part of your metric. Record the model, the prompt and the settings. Change any of them and your scores can move, as the 27 points show.
- Run your check more than once. If scores move several points between identical runs, a 3-point improvement means nothing.
- Use temperature 0 if your model allows it. For 1-to-5 scores, run three times and take the most common score.
- Write your strictness into the marking guide. Several splits came from questions the guide didn't answer, such as "does general advice count as unsupported?"
- Price isn't accuracy, but it isn't nothing. Sol was right on every clear item. gpt-oss missed one subtle wording error in most runs, at about a ninth of the cost and a sixth of the time (median 0.36 s a mark against 2.27 s). Whether that trade is right depends on your items, so test it on them.
You can test any AI task this way
- Write 20 to 30 examples, each with the answer you expect. Include some borderline ones on purpose.
- Run each example through the model several times. Five to ten runs is plenty.
- Count how often it was right, how often it gave the same answer every time, and where different models disagree.
- Read the model's reasons where it disagrees with you. Sometimes you're the one who's wrong.
Limits
- 30 items is a small test. On 12 items, one mistake is about 8 percentage points.
- The documents are short, about 250 words each. Long documents may behave differently.
- Each check used one prompt, at low reasoning effort.
- The right answers are my own marks, and as you've seen, I got some wrong.
One number: 27 points. That's how far the pass rate moved when I swapped one judge for another.
Because judges disagree like this, my next experiment marked every answer by code instead, and asked when a cheap model needs a bigger one: I didn’t need the expensive model. I needed to know when to call it..
Code and data: all 60 items, every mark and a notebook that reproduces each number here. Python only, bring your own API key; the second round cost me about $0.60
Related: I swapped the AI model and every test still passed. That was the problem. · Nothing found isn't the same as nothing checked · I didn’t need the expensive model. I needed to know when to call it.
Free: the AI Workflow Readiness Checklist, 32 questions to ask before you build
Do you use one model to check another's work? Have you tested whether it agrees with itself, or with a different judge?
First published 24 Oct 2026. Updated 25 Oct 2026: shortened, with the full score grids moved to GitHub and phone-readable charts; the findings are unchanged.
AI engineer with 14 years across machine learning and applied AI: prompt design, document AI, LLM workflows and the review loops that make them safe to ship. I build real systems and write up what breaks along the way.
Get the next note by email
One short email when something ships or breaks. Free.