Agents & workflows Lesson
My AI agent called a fined bank “medium risk”. No model made that call.
A schema checks the shape of an answer, not whether it is true. How a default value hid two failures in my agent, and the rules I follow now.
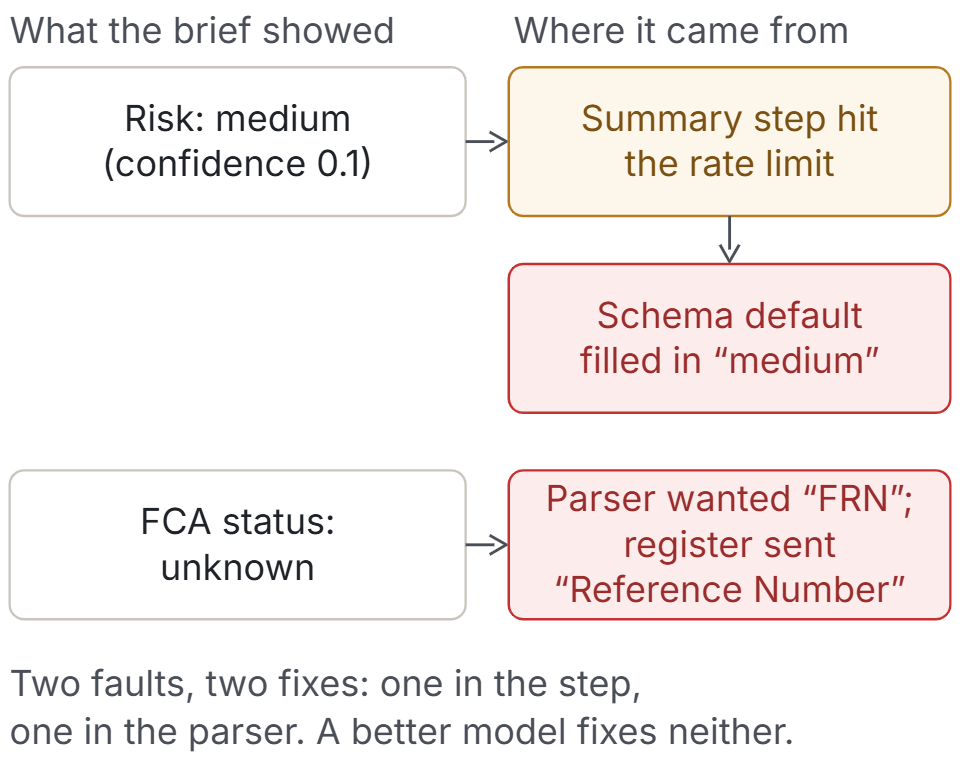
• My research agent rated Monzo, a bank the FCA had fined £21m, as “medium” risk. No model chose “medium”: the step that should have rated it failed, and my schema filled in its default.
• The same brief called Monzo’s FCA status “unknown”, because my parser looked for the wrong field name. Two faults with two different fixes, and a better model would have fixed neither.
• Now a failed assessment leaves the field empty and says why. Any value that can change someone’s next action has to show where it came from.
My first company research agent took 74 seconds to write a brief about Monzo, a bank the FCA fined £21m in 2025. The headline rating was medium, with a confidence score of 0.1. Reading it, I could easily have assumed the model had weighed the evidence and reached a tentative view.
I went looking for the answer in which the model had chosen “medium”. There wasn’t one.
This was version 1 of my UK company tool, a research agent that decided the risk itself; Version 1 let an AI agent decide. Version 2 lets written rules decide. explains why I replaced it.
How a failed step became a rating
The agent worked in steps. One read news articles. Another wrote a summary and supplied the risk level. On the Monzo run, the news step returned a reply the software couldn’t read. The summary step then hit the model provider’s limit on requests. The program carried on with what it had.
I’d used Pydantic, a Python library, to describe the fields in the report. Think of it as a form with rules about which boxes accept numbers and which accept text. I’d given the risk box a starting value: “medium”. When the summary step supplied nothing, the report kept the value I’d chosen.
The form passed validation. There really was a value in the risk box, and it was one of the allowed ones. The low confidence number didn’t help with the question that mattered: had anything actually assessed the risk?
A second fault in the same report
The brief also gave Monzo’s regulatory status as unknown. That field had its own history. My code looked for the firm reference number under the name “FRN”. The register’s reply put it under “Reference Number”. The parser missed a value that was already there, so the report failed to recognise an authorised bank.
A better model could help the summary step finish. It could do nothing about a field name in my parser. That’s why I’d debug the two separately: one needs a test that withholds the summary, the other needs a saved register response with the real field name.
What I’d show the reader
If the assessment step fails, the risk field should stay empty and the report should say so: “Risk assessment unavailable. The summary request failed.” That gives a reviewer a reason to retry or take over, and it lets me count how often the step fails instead of hiding those cases in a pile labelled medium. Nothing found isn’t the same as nothing checked is the same idea applied to checks.
I met a smaller version in PolicyTrace, my insurance-document project. A yes-or-no field recorded whether someone was the main driver. When the document said nothing about a person, a default of “no” filled in an answer the document never gave. A third value, “not stated”, kept that difference for the person reviewing the record.
A test that takes one missing answer
Choose a field people use to make a decision. Remove the upstream answer and render the report. What appears in the most prominent box? Could a colleague tell a real assessment from a value your code supplied?
I’d keep the validation; it helped me trace what happened. But in the rebuilt pre-screen, the route comes from a written rule applied to recorded check results, so I can trace every route to a rule. On the old Monzo report I could trace “medium” just as precisely. It led all the way back to me.
Limits
- One run, on 18 Oct 2026, on a free model tier. Under the same limits, two users at once would hit them more often.
- Pydantic checks the shape of an answer, not whether it’s true. That stays true with or without defaults.
- An empty field is only better if the screen says why it’s empty and someone acts on it.
Code: the Pre-Screen on GitHub (version 1’s baseline runs are in docs/rebuild)
System: how the Pre-Screen works, and what it can’t do yet
Related: Nothing found isn’t the same as nothing checked · Version 1 let an AI agent decide. Version 2 lets written rules decide.
Free: the AI Workflow Readiness Checklist
Which field in your reports would still show a value if the step that sets it failed?
First published 24 May 2026. Updated 8 Nov 2026: retold as a trace from the rating back to the line that set it; the findings are unchanged.
AI engineer with 14 years across machine learning and applied AI: prompt design, document AI, LLM workflows and the review loops that make them safe to ship. I build real systems and write up what breaks along the way.
Get the next note by email
One short email when something ships or breaks. Free.