Documents Lesson
Only one of my PDF problems was in the model
When a PDF extraction goes wrong, the model is the obvious suspect. In my system, four of the five real problems were in the ordinary code around it.
• Over a few days of runs, PolicyTrace hit five problems worth fixing. Only one was in the model call.
• The rest came from the parser, the masking, my merge code and my matching code: ordinary software, between the PDF and the model and after it.
• So when a PDF extraction goes wrong, I now check the plumbing first. It's where most of the bugs were, and it's the part I can test.
When an extraction from a PDF goes wrong, my first instinct used to be to blame the model. A better prompt, a bigger model. PolicyTrace cured me of that.
PolicyTrace is a small system I built to read a UK car insurance policy pack, usually four PDFs, and return one record of the facts a claims handler needs: who is insured to drive, what the excesses are, when cover starts. Every value is linked to the line in the PDF it came from. Over a few days of runs on its demo pack, I wrote down every problem worth fixing. There were five, and only one was in the model call.
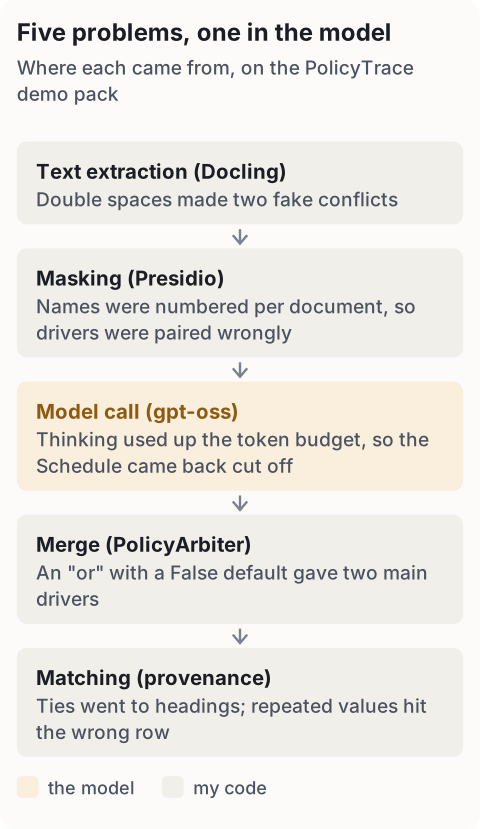
1. Text extraction: a double space
The first full run reported four disagreements between two of the documents. Two were the same text with a double space in one copy, left behind when the PDF was turned into text. My comparison trimmed and lowercased values but never collapsed spaces inside them. A one-line fix, and an important one: a reviewer who sees fake conflicts on every pack soon stops reading them. The full story of those four conflicts.
2. Masking: names numbered per document
Before any text reaches the model, names are replaced with tokens like MASKED_PERSON_2. That's the point of masking, but the tokens were numbered separately in each document, so the merge paired drivers with the wrong person. Now one person gets one token across the whole pack. A side effect remains: a token never appears on the page, so names never get a highlight.
3. The model call: the answer ran out of room
This is the one that was in the model. When I moved to the gpt-oss models on Groq, a full Schedule came back cut off halfway. gpt-oss is a reasoning model: it writes out its thinking before its answer, and both count against the same limit on output length. With the default limit, the thinking used up the room the answer needed.
What made it nasty is how it looked. Half a record, with every missing field reading as "not in the document". Nothing errored. A 4,096-token limit and the model's low reasoning-effort setting fixed it. The check I'd add: compare how many fields came back against how many the document type normally has, and treat a sudden drop as a failure, not as an empty document.
4. The merge: an "or" and a default
The record ended up with two main drivers. The line that merged the two documents set the flag with schedule or certificate, and the default value was False, so the code couldn't tell "no" from "not stated". I only noticed because the merge had logged a conflict that the record contradicted. Defaults hiding missing values turned out to be a pattern, not a one-off.
5. Matching: ties went to the wrong place
The model quotes the phrase it used, and plain code finds that phrase on the page. In the driver table, a column header and a label scored as well as the driver's own row, and on a tie the first one on the page won. Repeated values such as "GBP 200.00" landed on the wrong driver. A ranking change fixed it. The details are here.
What I take from it
Most of the work in getting facts out of PDFs sits around the model, not inside it. What does the parser keep? What does masking hide? How are two documents merged? How is a value found again on the page? Each of those is ordinary code that I can read and test, and four of the five fixes came with tests that fail on the old code. That's why I keep those decisions outside the prompt.
The one model problem had something in common with the others, too: it failed quietly. Every one of the five produced output that looked plausible. None of them threw an error.
Limits
This is one system on a synthetic pack of native PDFs, which I generated myself. I haven't tried scanned documents, and OCR would add a sixth kind of problem. Five problems is a count from my own notes, not a measured failure rate. On the 18 October run, 46 of 59 fields were traced to a line in the PDF.
Code: PolicyTrace on GitHub
Demo: the live demo runs the same pack in about three minutes
Related: What happens to a PDF inside PolicyTrace · Two documents, one policy, four disagreements
Free: the AI Workflow Readiness Checklist, 32 questions to ask before you build
If your own PDF pipeline broke, where did it break? I'd like to hear.
First published 24 May 2026. Updated 25 Oct 2026: rewritten as a short guide to five problems, each linking to its full write-up; new diagram.
AI engineer with 14 years across machine learning and applied AI: prompt design, document AI, LLM workflows and the review loops that make them safe to ship. I build real systems and write up what breaks along the way.
Get the next note by email
One short email when something ships or breaks. Free.